
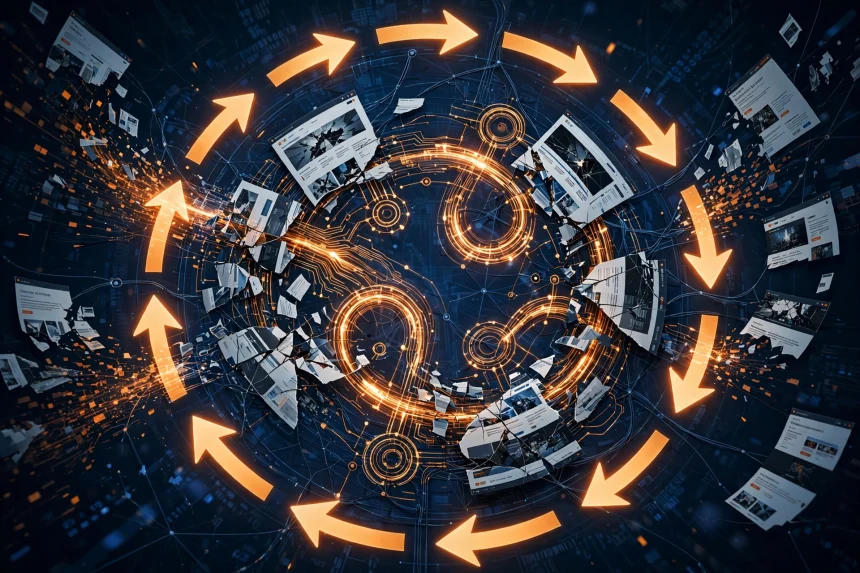
The open web was built on a simple exchange: people created pages, search engines sent readers to those pages, and advertising or subscriptions paid the bills. That exchange is now under strain from a problem researchers and publishers increasingly call the AI “doom loop” — a cycle in which automated systems generate enormous volumes of content, other automated systems train on it, and the quality and economics of the original web quietly erode. Recent reporting on internal Microsoft documents has given the idea fresh urgency, suggesting that even the companies building these tools have worried about what happens when machines start learning mainly from machines.
What the doom loop actually means
The concern is not that AI tools exist, or that newsrooms use them. Used carefully, automation can transcribe interviews, summarise documents, translate stories and free reporters to do work that requires judgement. The doom loop describes something different: a feedback cycle. Models are trained on the public web. Those models then produce text, images and video at almost no cost. That material floods websites, social feeds and search results. The next generation of models trains on a web that contains more and more synthetic material, including its errors, clichés and invented facts.
Researchers have a name for part of this effect: model collapse. When systems repeatedly learn from generated output rather than from fresh human evidence, unusual voices, minority viewpoints and rare facts tend to disappear first. The average survives; the distinctive fades. For a media industry that sells distinctiveness — a reporter who was actually there, a photographer who actually saw it — that is not a theoretical risk. It goes to the heart of what audiences pay attention to, a theme we explored in our look at the future of online entertainment and how platforms compete for trust.
Why publishers feel it first
Publishers sit at both ends of the loop. Their archives are among the most valuable training material on the web, because professionally edited text is cleaner than the average page. At the same time, their businesses depend on being found. If AI-generated answers satisfy a reader’s question without a click, the publisher loses the visit, the advertising impression and the chance to build a habit. If AI-generated articles crowd search results, original reporting must compete with content produced at near-zero marginal cost.
The result is a squeeze that many editors now describe in similar terms: production is cheaper than ever, but distribution is harder than ever. Newsrooms that respond by publishing more, faster, with thinner verification risk feeding the very cycle that is hurting them. A detailed account of the Microsoft documents and the wider debate has been reported by The Cool Down, and the discussion has spread quickly through media and technology circles this week.
The economics underneath the technology
Strip away the technical language and the doom loop is an economics problem. The web’s content ecosystem worked because creating good information was expensive and copying it was comparatively visible. Generative AI reverses parts of that equation. Copying style, structure and substance is now cheap, while proving originality — sending the reporter, checking the document, photographing the scene — remains expensive.
That imbalance explains why licensing deals, paywalls, crawler controls and legal disputes have become central to media strategy. Large publishers can negotiate. Small publishers, local outlets and independent creators usually cannot, yet their work is often the most original material in any given community. If the loop rewards volume over verification, the outlets least able to absorb the shock are the ones producing the information everyone else repeats. The same dynamic shapes how audiences gather around trusted sources, something we noted in our coverage of how online communities are shaping modern entertainment and media habits.
What a healthier loop could look like
None of this is inevitable. The technology’s direction depends on choices made by platforms, publishers and regulators. Clear labelling of synthetic content would help readers and researchers measure the problem. Stronger provenance standards — cryptographic signatures showing where an image or article came from — would make original work easier to identify and license. Search and recommendation systems could weight first-hand evidence more heavily instead of rewarding whoever publishes the most variations of the same claim.
Inside newsrooms, the practical response is equally clear. Use automation for tasks where errors are cheap and checkable: transcription, data cleaning, translation drafts, archive search. Keep humans visibly responsible for tasks where errors are expensive: allegations, investigations, medical and financial advice, and anything carrying a person’s reputation. Publish the evidence, not just the conclusion.
The bottom line for readers and publishers
The doom loop warning matters because it reframes a familiar debate. The question is no longer simply whether AI will replace journalists, designers or photographers. It is whether the information environment itself stays healthy enough for anyone — human or machine — to learn from. A web filled with confident, plausible, unverified material trains bad models and misleads real people at the same time.
Publishers cannot solve that alone, and AI companies cannot solve it by generating more of the same. The outlets most likely to thrive are those that treat originality as infrastructure: first-hand reporting, transparent corrections, distinctive voices and direct relationships with readers. In a loop that rewards sameness, being verifiably real may turn out to be the strongest business model the web has left.